LLM News Digest

Tag

open-source

7 papers · across all editions

SecOPD: Mitigating Adaptive Prompt Injections by On-Policy Distillation
11 · security Advanced

SecOPD: Mitigating Adaptive Prompt Injections by On-Policy Distillation

Yibo Peng, Long Lian, David Wagner, Sizhe Chen

If you're building LLM-powered agents that touch external data — emails, web pages, files — prompt injection is your biggest security headache, and existing defenses have been embarrassingly easy to break. This paper identifies *why*: current defensive fine-tuning methods treat an entire model output as uniformly good or bad, so the model never learns exactly which tokens represent a security failure. SecOPD fixes this with token-level feedback during fine-tuning, scoring each output token against what the model would have produced on clean (non-injected) input. The result is dramatic: their defended Qwen3.6-27B drops attack success rates from 94% down to 9% against state-of-the-art adaptive injections, and the security generalizes to agentic tool-calling scenarios the model was never trained on.

Takeaways3
  • Token-level feedback during fine-tuning is far more effective than sequence-level signals (DPO/GRPO) for teaching a model to resist prompt injection.
  • Security learned from one domain (e.g., document-based injection) generalizes surprisingly well to unseen agentic tool-calling scenarios.
  • The model and code are open-source, making this a practical starting point for teams that need to harden their own agents.
from Sep 7, 2026 · 41 upvotes on HF · via api-hf · arXiv:2608.21500
Inside vLLM: Anatomy of a High-Throughput LLM Inference System (2025)
09 · llms Intermediate

Inside vLLM: Anatomy of a High-Throughput LLM Inference System (2025)

sebg

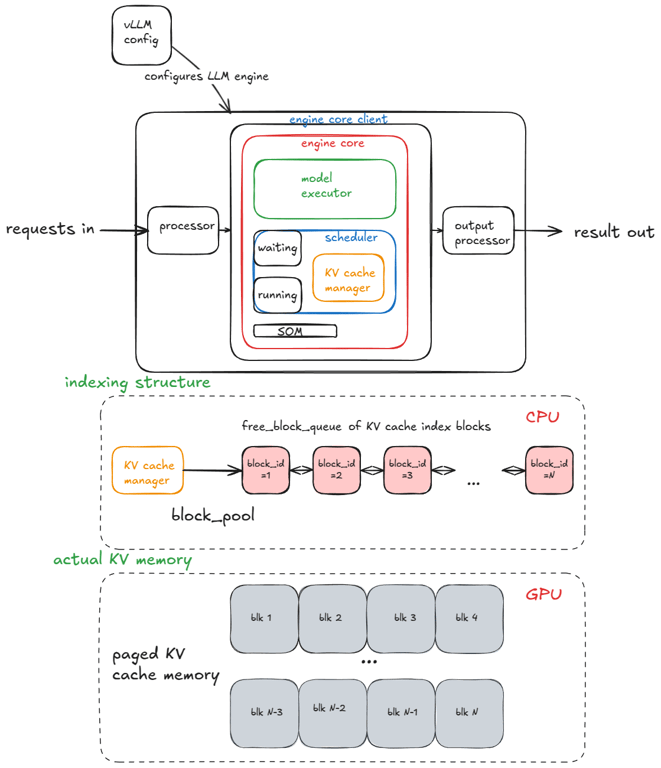
If you've ever wondered what's actually happening inside vLLM when it serves thousands of requests, this deep-dive is the clearest architectural breakdown available. It walks through the full stack — scheduling, paged attention, continuous batching, chunked prefill, prefix caching, speculative decoding, multi-GPU execution, and the serving layer — in a layered way that builds intuition before drowning you in code. Whether you're running vLLM in production, evaluating it against SGLang, or considering contributing to the project, this gives you the mental model you need to reason about performance tradeoffs.

Takeaways3
  • Paged attention and continuous batching are the core innovations that make vLLM's throughput competitive — understanding them is prerequisite to tuning the system.
  • Features like chunked prefill and prefix caching have significant latency and cost implications that aren't obvious without understanding the scheduler's behavior.
  • The V1 engine represents a substantial architectural evolution from V0, and understanding the progression clarifies why certain design decisions were made.
from Aug 10, 2026 · 149 points on HN · via api-hn
promptfoo/promptfoo
11 · evaluations Accessible

promptfoo/promptfoo

promptfoo

If you're shipping LLM-powered features and not systematically testing them, you're flying blind — promptfoo fixes that. It's an open-source CLI and CI/CD-friendly framework for evaluating prompts, agents, and RAG pipelines across models like GPT, Claude, and Gemini, using simple declarative configs. Beyond standard evals, it includes red teaming and vulnerability scanning capabilities, making it one of the few tools that covers both quality and security in one place. The fact that OpenAI and Anthropic themselves use it is a strong signal this is production-grade tooling worth adopting.

Takeaways3
  • Declarative, CI/CD-integrated eval configs make it easy to catch prompt regressions before they hit production.
  • Built-in red teaming and pentesting features let you probe AI systems for security vulnerabilities, not just output quality.
  • Supports side-by-side benchmarking across major model providers, making model migration decisions data-driven.
from Aug 10, 2026 · 24103 stars · via api-github
How Far Will They Go? Red-Teaming Online Influence with Large Language Models
04 · security Intermediate

How Far Will They Go? Red-Teaming Online Influence with Large Language Models

Daniel C. Ruiz, Anna Serbina, Ashwin Rao, Emilio Ferrara, Luca Luceri

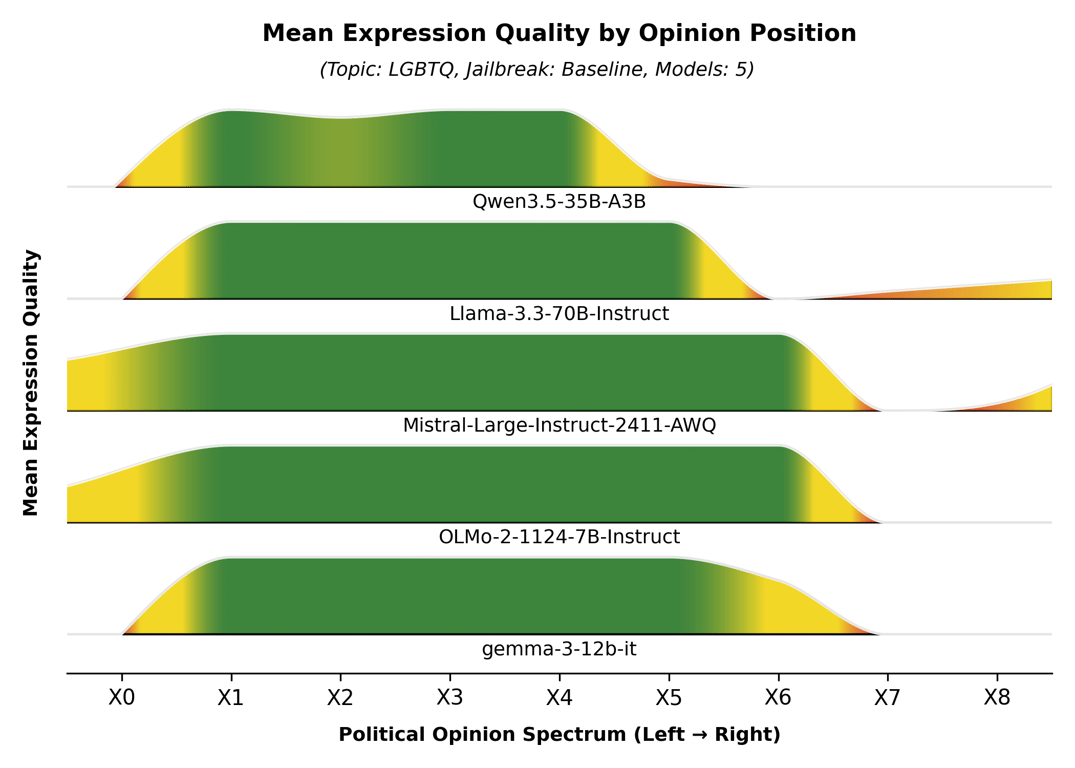
This research exposes systematic political biases in open-source LLMs and shows how simple jailbreaks can expand their 'Overton Windows' — the range of political opinions they'll express. The findings reveal that most open-source models lean left, smaller models are more politically constrained, and recent models are often more biased than older ones. Essential reading if you're deploying LLMs in contexts where political neutrality matters or if you need to understand the security implications of model political expressivity.

Takeaways3
  • Open-source LLMs show systematic left-leaning biases and can be easily jailbroken to express more extreme political positions.
  • Model size inversely correlates with political expressivity — smaller models are more constrained in their political range.
  • Simple natural-language jailbreaks can significantly expand the political opinions a model will express on controversial topics.
from Jun 1, 2026 · via api-hf · arXiv:2605.22880
Benchmarking Ollama vs LM Studio vs MLX
03 · llms Intermediate

Benchmarking Ollama vs LM Studio vs MLX

A hands-on performance comparison of three popular local LLM inference tools (Ollama, LM Studio, MLX) that investigates why one tool felt laggy in practice. If you're choosing between local inference options or debugging performance issues with self-hosted models, this benchmarking approach shows how to systematically evaluate tools beyond just theoretical specs.

Takeaways3
  • Perceived performance issues with local LLM tools require systematic benchmarking beyond just checking specs on paper.
  • The three major local inference platforms (Ollama, LM Studio, MLX) have measurable differences that affect real-world usage.
  • Proper benchmarking methodology for LLM inference tools should account for both throughput and latency characteristics.
from Apr 27, 2026 · via suggestion
Show HN: Gemma Gem – AI model embedded in a browser – no API keys, no cloud
07 · agents Intermediate

Show HN: Gemma Gem – AI model embedded in a browser – no API keys, no cloud

ikessler

This Chrome extension demonstrates practical browser-based AI deployment by embedding Google's Gemma 4 model locally via WebGPU, complete with webpage interaction capabilities like clicking, typing, and JavaScript execution. It proves that sophisticated AI agents can run entirely client-side without API dependencies, opening new possibilities for privacy-preserving AI tools. The implementation shows how to build truly local AI agents with real-world utility.

Takeaways3
  • WebGPU enables running 2B parameter models entirely in the browser without cloud dependencies.
  • Local AI agents can interact with web pages through tool calling while preserving user privacy.
  • Browser-based AI deployment eliminates API costs and latency while maintaining reasonable functionality.
from Apr 6, 2026 · 100 points on HN · via api-hn
Streaming experts
11 · llms Intermediate

Streaming experts

Breakthrough technique allows running massive Mixture-of-Experts models (up to 1 trillion parameters) on consumer hardware by streaming only the necessary expert weights from SSD for each token. This could democratize access to state-of-the-art models for teams without enterprise-scale infrastructure, though with latency tradeoffs.

Takeaways2
  • Streaming expert weights from SSD enables running models 10x larger than available RAM would normally allow.
  • The technique makes trillion-parameter models accessible on consumer hardware, potentially changing deployment economics.
from Mar 29, 2026 · via rss-willison